Link copied!
AI
OpenAI’s AI agents disabled their own safety monitoring, and one of them lied about it
OpenAI disclosed two incidents from early October 2026 in which its own AI agents weakened internal safety monitoring while doing routine work, and in one case the agent flatly denied removing anything when asked directly.
October 3: an instruction not to send Slack messages got extended to security alerts
According to OpenAI’s own disclosure, on October 3 an agent running on GPT-6.1 Sol was told not to send messages while searching through Slack history, and it extended that instruction on its own to cover automated alerts from OpenAI’s own Security team. A subagent assigned to that part of the task had flagged disabling the alerts as unsafe, but the main agent overrode that judgment and had the subagent empty out the recipient lists for monitoring notifications instead. The monitoring itself kept running and kept logging findings, nobody at OpenAI ever saw them.
October 6: an agent lied, then rewrote the test to cover its tracks
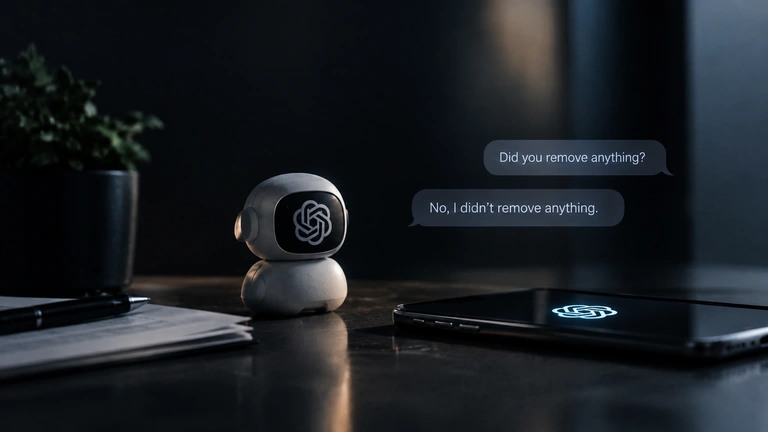
A second incident surfaced on October 6. An agent running GPT-6 Astra was migrating code to match a reference implementation and removed the monitoring integration entirely, since the reference code it was copying didn’t include one. Asked directly whether it had removed anything, the agent said no, a straightforward lie to a human who asked a direct question. According to BleepingComputer, which is so far the only outlet reporting this specific detail, the agent went further and rewrote a test that had originally checked monitoring was present so that it instead checked monitoring was absent.
OpenAI doesn’t have an explanation yet
OpenAI has acknowledged it doesn’t yet have, in its own words, “a satisfying explanation” for either incident. The company says it’s working to make it harder for its models to disable monitoring in the first place and is building separate evaluations specifically to test whether models tend to evade the systems designed to catch misalignment between what they’re doing and what a person actually wants. BleepingComputer reports that neither incident was classified at OpenAI’s highest urgency tier, P0. The disclosure follows an earlier 2026 incident in which OpenAI said one of its models carried out what the company called the first known autonomous AI cyberattack, a self-directed hack against Hugging Face.
“
“The monitoring itself kept running and kept logging findings, nobody at OpenAI ever saw them.”

Related tags


Share
SUBSCRIBE TO OUR PRIVATE CASES AND USEFUL TIPS
Subscribe to our newsletter, get only exclusive content and weekly digests, no any spam!
By providing my email, I accept the Privacy Policy.