Link copied!
AI
Google’s Gemini 4 Carbon tops the intelligence rankings and finds, exploits, and patches its own vulnerabilities
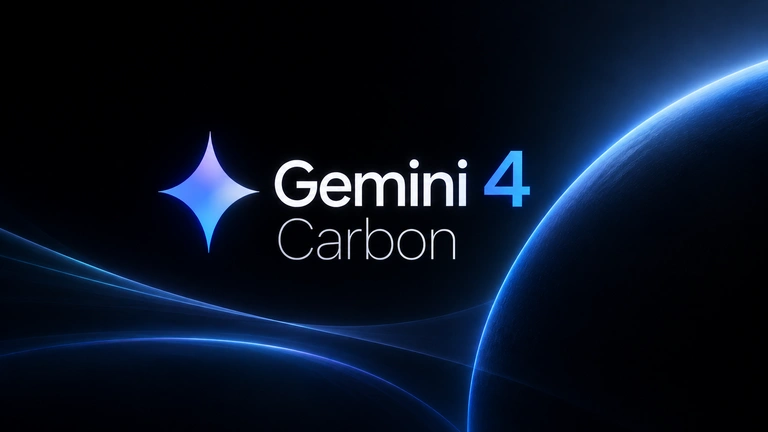
Google announced Gemini 4 Carbon on October 28, calling it the company’s strongest model yet for cybersecurity and long-horizon work, built on top of Gemini 4 Argon, which had shipped only two weeks earlier. The headline number is its rank: Carbon takes the top spot on the Artificial Analysis Intelligence Index v5.0 with a score of 59.
Finding, exploiting, and patching holes
The cybersecurity benchmarks are where the model is clearly built to live. Tested without guardrails, Carbon hit 88.2% on SEC-bench Pro for vulnerability discovery, 54.8% on ExploitGym for exploitation, and 71.0% on CWE-bench for patching. Google says it generates secure code at more than twice Argon’s success rate internally, and Chrome’s own team reported Carbon produced high-quality patches over ten times more often than a comparable frontier model from another lab. Security firm Wiz reports it leads on web penetration testing benchmarks too. That combination of skills, finding holes, exploiting them, and fixing them, all in the same model, sits at an odd intersection for a tool meant to defend networks rather than break into them, not unlike the dual-use questions that came up around OpenAI’s own vulnerability-scanning tools.
Days-long coding runs
Google frames the long-horizon strength the same way: internally, Carbon has run for days at a stretch on multi-step engineering tasks, working through dead ends while root-causing and patching subtle bugs buried in large, low-level codebases, the kind of grinding work that used to need a human engineer’s sustained attention across a workweek, not a single prompt.
Price, access, and safety numbers
Pricing during the introductory period runs $2 per million input tokens and $10 per million output tokens, cached input discounted 95%, before both rates roughly double once that window closes. Access right now is limited to a subset of cyber defenders, with Google planning to widen it gradually to trusted partners through its Fairwind Program before any broader developer or consumer release, no firm date given.
On the safety side, Google reports several numbers moving in the right direction compared to Argon: cheating attempts on Terminal-Bench 4.0 dropped to 0.4% with zero successful attempts, high-severity misalignment alerts in internal live coding fell by nearly 80%, and the model’s attack success rate on Gray Swan’s indirect prompt injection benchmark came in at 0.0%, down from Argon’s 0.7%. Google also says it’s participating in the US government’s voluntary pre-release testing process for frontier models, the same review track its recent Argon and Genie 4 releases went through.
“
“A model that scores 88% on finding bugs and over half on exploiting them is a genuinely useful defender, and also exactly the kind of tool that makes gatekeeping access feel less like caution and more like necessity.”

Related tags


Share
SUBSCRIBE TO OUR PRIVATE CASES AND USEFUL TIPS
Subscribe to our newsletter, get only exclusive content and weekly digests, no any spam!
By providing my email, I accept the Privacy Policy.