Link copied!
AI
ElevenLabs launches Eleven v4, a voice model that reads scripts like an actor
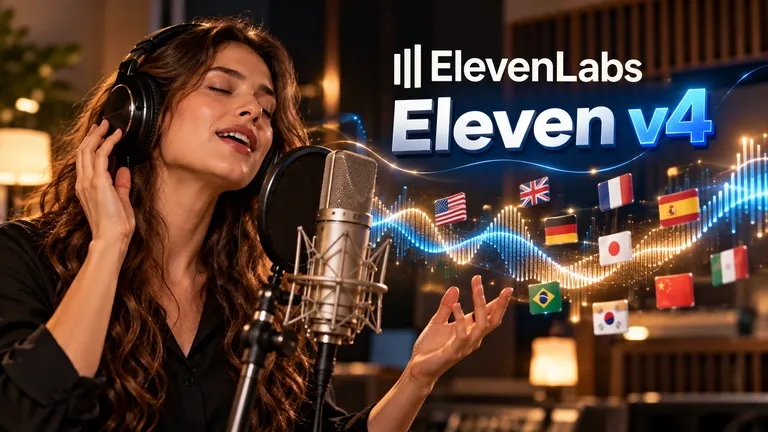
ElevenLabs released Eleven v4 on September 28, a text-to-speech model built to track a scene’s context and emotional weight the way a voice actor would, alongside a faster Turbo variant aimed at real-time voice agents.
Reading a script instead of a sentence
ElevenLabs released Eleven v4 and a faster Turbo variant on September 28, positioning both as the most expressive text-to-speech models the company has shipped. The core pitch is that v4 reads a script the way a voice actor would, keeping track of who’s speaking, what just happened in the scene, and what emotional weight a line is supposed to carry, rather than converting text to audio one sentence at a time in isolation.
That context-awareness shows up most in longer projects. ElevenLabs says a full audiobook chapter now comes out sounding like a single continuous take rather than a string of separately generated clips stitched together, and that speaker identity holds steady across regenerated lines instead of drifting the way earlier models sometimes did after repeated passes. Inline tags carried over from v3 got an upgrade too: writers can stack multiple delivery tags, covering things like laughter, whispering, pacing, and sound effects, and have the model follow them in sequence rather than picking up just the last one.
90 languages, and independent numbers to back it up
Language coverage jumped from 70 to 90, with ElevenLabs pointing to Japanese, Brazilian Portuguese, Mandarin, and Cantonese as the biggest quality gains. Turbo, the companion release, trades some of that nuance for speed, aimed at real-time use cases like voice agents rather than narration, with a reported median time to first speech around 150 milliseconds.
None of this comes only from ElevenLabs’ own marketing. Independent testing from Artificial Analysis ranked v4 first on its Provider Voice Arena leaderboard for September, and the company says blind listener tests preferred it over competing models roughly 75 percent of the time. Both models are live now across ElevenLabs’ agent, creative, and API products.
“
“A voice model that holds a character steady for an entire audiobook is worth more than one that just sounds good for a ten-second demo clip.”

Related tags



Share
SUBSCRIBE TO OUR PRIVATE CASES AND USEFUL TIPS
Subscribe to our newsletter, get only exclusive content and weekly digests, no any spam!
By providing my email, I accept the Privacy Policy.